Comparing state of the art LLMs for 3D generation
Updated October 2026. This post started in November 2025 as a three-way fight between GPT-5, GPT-5.1 and Gemini 3. Since then I've run the suite against more than thirty model and settings combinations and changed the default model six times. The current table is first; the original November 2025 numbers are kept at the end as a snapshot.
For GrandpaCAD, my text-to-3D tool, there is exactly one question I need a language model to answer: can it write CAD code that compiles into a printable object the user asked for, quickly, and without costing more than the user paid? Public benchmarks don't measure that, so I run my own.
How the test works now
The suite replays 23 scenarios through the production chat agent with the real CAD tools, nothing mocked: thirteen one-shot parts (a threaded jar, a Pi 4 case, a pegboard hook, a chess queen, a coffee cup), five multi-turn builds where the user refines the part over several messages (a phone stand, a dice tower, a bird house), four parameter-editing flows, and one organic-plus-CAD combination. When the generated code throws, the error goes back to the model and it retries inside the same turn, exactly like a real session. The methodology post has the scoring scale.
Three things changed since 2025. First, every run is graded by me, by hand, on a 0 to 1 adherence scale. I used to let a second model judge, until I checked it against seven fully human-graded runs: the judge overrated every run, and it overrated the worst models the most (0.27 too high for the weakest, 0.05 for the strongest). Ranking by judge score produced close to the reverse of the human ranking, so the judge is off. Second, each scenario has deterministic checks that no opinion can argue with: did a file come out, how many code errors, was it under the cost and time budget. Third, every run logs its cost and wall clock per model, which is what actually decides what I ship.
October 2026: the current ranking
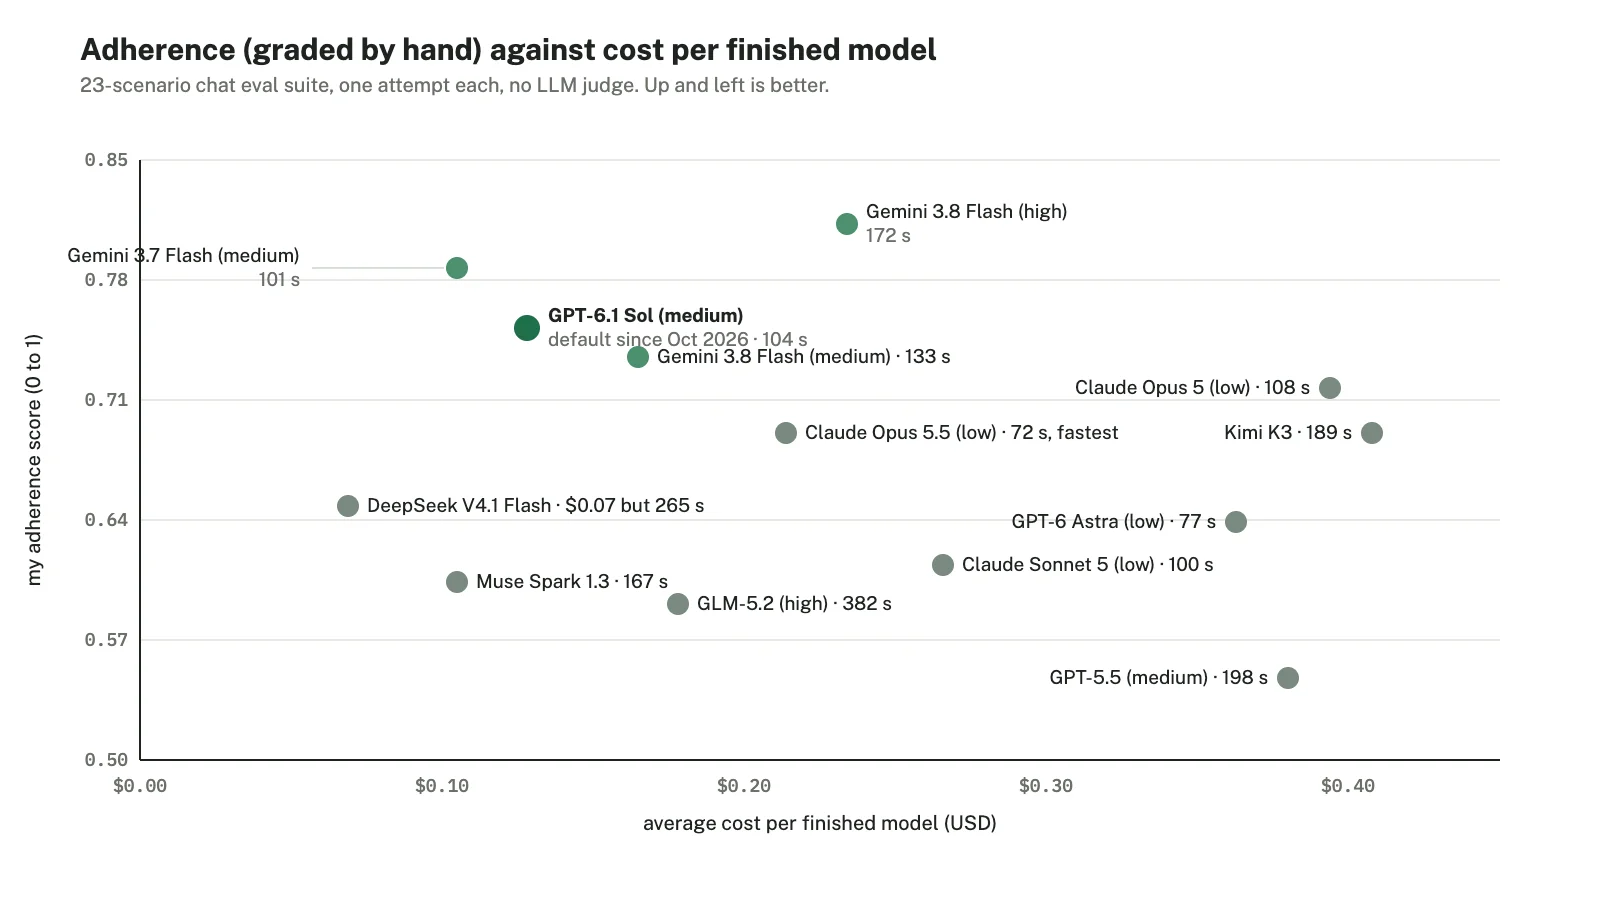
Every point below is one full pass of the suite, one attempt per scenario, graded by hand. Cost is the average per finished model including retries. Time is the average wall clock from prompt to file.
| Model (reasoning) | Adherence | Checks passed | Code errors | Avg cost | Avg time |
|---|
| GPT-6.1 Sol (medium)default since October 2026 | 0.75 | 91 / 106 | 1 | $0.13 | 1m 44s |
| Gemini 3.8 Flash (high) | 0.81 | 87 / 106 | 8 | $0.23 | 2m 52s |
| Gemini 3.7 Flash (medium)default August to September 2026 | 0.79 | 97 / 106 | 10 | $0.11 | 1m 41s |
| Gemini 3.8 Flash (medium) | 0.74 | 90 / 106 | 9 | $0.17 | 2m 13s |
| Claude Opus 5 (low, Anthropic direct) | 0.72 | 87 / 106 | 1 | $0.39 | 1m 48s |
| Claude Opus 5.5 (low)fastest | 0.69 | 93 / 106 | 10 | $0.21 | 1m 12s |
| Kimi K3 (low) | 0.69 | 84 / 106 | 8 | $0.41 | 3m 09s |
| DeepSeek V4.1 Flash (low)cheapest | 0.65 | 89 / 106 | 13 | $0.07 | 4m 25s |
| GPT-6 Astra (low) | 0.64 | 93 / 106 | 1 | $0.36 | 1m 17s |
| Muse Spark 1.3 (medium) | 0.60 | 87 / 106 | 3 | $0.11 | 2m 47s |
| GPT-5.5 (medium)5 scenarios produced no model | 0.55 | 71 / 106 | 3 | $0.38 | 3m 18s |
One caveat on fairness: these runs span June to September 2026, and the prompts, skills and tooling around the agent improved over that period. Two prompts (the hex bracket and the pegboard hook) were tightened just before the GPT-6.1 Sol runs. Models tested later had a slightly easier harness. The gaps that matter below are bigger than that drift.
Why GPT-6.1 Sol is the default and Gemini 3.8 Flash isn't
If you only read the adherence column, Gemini 3.8 Flash on high reasoning wins. It produced the models I liked best (0.81). It also wrote code that errored eight times across 23 scenarios, took almost three minutes per model, and cost nearly twice as much as GPT-6.1 Sol.
GPT-6.1 Sol errored once. Once, in the whole suite. A code error is not an abstract metric: it's a user watching a spinner while the agent repairs its own script, and every repair is another model call. Sol at 0.75 adherence, 1 error, $0.13 and 1m 44s is the combination I'd rather put in front of someone on their first free generation than 0.81 with a one-in-three chance of a visible retry.
There's a second reason that the suite only partly captures. Sol builds far more complex things than anything before it: multi-part assemblies, enclosures with every cutout in the right place, mechanisms where the pieces have to line up. The cost is creativity. Give it a vague prompt and you get a plain, literal part. I wrote up the trade in the switch post, with prompts that show it.
Gemini 3.7 Flash on medium is the one I'd still recommend if you run your own pipeline and cost is the constraint: the best deterministic pass rate in the table (97 of 106), $0.11 a model, and it was our default for two months. It lost to Sol on code errors (10 against 1) and on what it can build, not on price.
What a year of this taught me
More reasoning rarely helps, and often hurts. Gemini 3.7 Flash on high cut first-try code errors from 10 to 3 and still scored lower than medium, at higher cost and time. Claude Opus 5 on high reasoning was strictly worse than on low: 2.4x slower, 39% more expensive, five code errors instead of zero, and two scenarios killed by the ten-minute timeout. Back in 2025, GPT-5 on medium beat high for half the price. The extra thinking goes into thinking, not into the part.
The gateway isn't neutral. The same Claude Opus 5 at the same effort cost 35% less through Anthropic's own API than through OpenRouter, cheaper in 22 of 23 scenarios, with identical quality. The Opus 5 post has the probe that explains why.
Code errors predict the user's experience better than my adherence score does. Adherence tells you whether the final part is right. Code errors tell you how long the user waited and how many model calls I paid for to get there. When two models are within 0.05 of each other on adherence, the error column decides.
Public leaderboards disagree with this table every time. In April, Kimi K2.6 topped a public 3D ELO chart and finished last on real work, while Opus 4.7 looked slow and expensive on paper and won outright. That post lists the four ways the public numbers lie. Nothing since has changed my mind.
If you want to check any of this, every run, including the ugly ones, is on the evals page with the full transcript of every tool call.
The November 2025 snapshot
This is what the post originally said, kept as it was. It ran on the old single-shot pipeline (one prompt, one generation, no agent loop), with an AI judge for adherence instead of my own grading, which is why the numbers aren't comparable with the table above.
GPT-5 (August 7), GPT-5.1 (November 12) and Gemini 3 (November 19) had all shipped within four months. I ran 84 generations on each. I burned through 6 million tokens on Gemini 3 in the first 24 hours of its release alone.
| Metric | Gemini 3 | GPT-5 | GPT-5.1 |
|---|
| Weighted score | 0.555 | 0.501 | 0.467 |
| Pass rate | 79.76% | 80.95% | 67.86% |
| Adherence (AI judge) | 0.57 | 0.54 | 0.46 |
| Avg cost | $0.14 | $0.18 | $0.26 |
| Avg time | 1m 24s | 3m 26s | 1m 12s |
| Total cost (84 runs) | $12.05 | $15.40 | $22.13 |
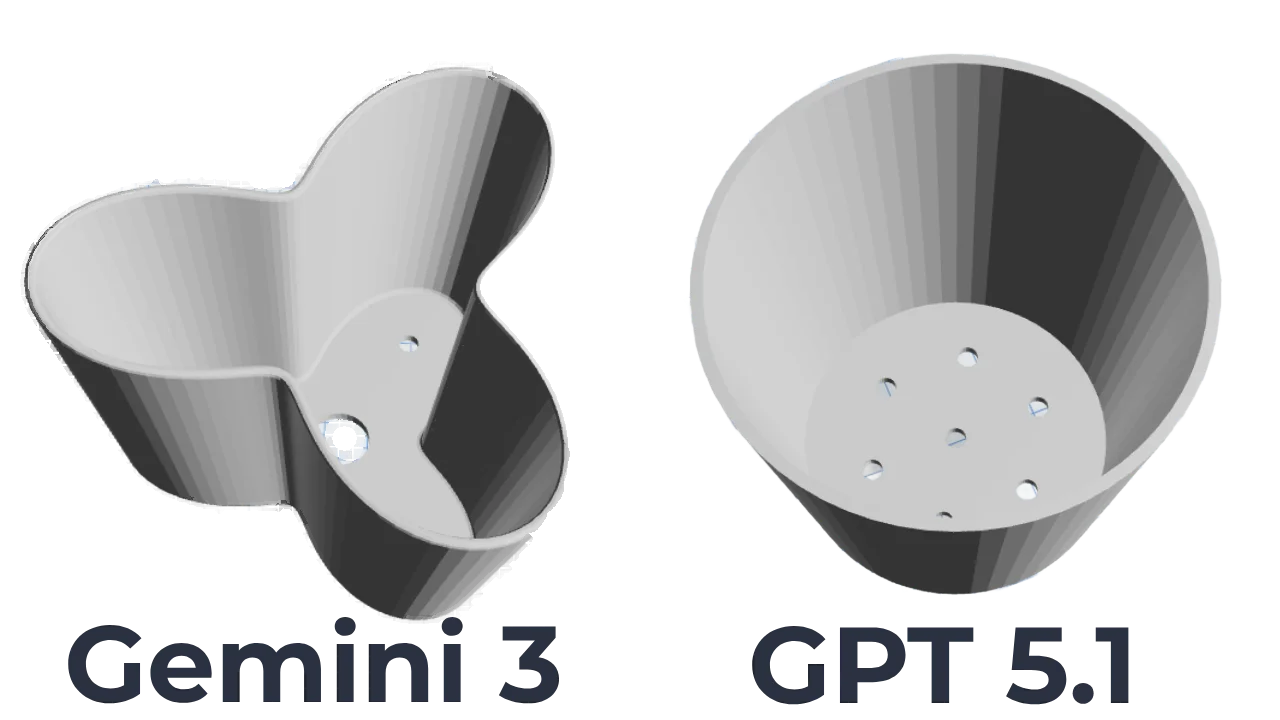
Gemini 3 won on weighted score, adherence and cost, and it felt different: when I asked for a "stackable 3D pot", earlier models gave me a cylinder with a lip, and Gemini 3 made something I'd actually stack. GPT-5.1 was fast but ran with OpenAI's priority tier, which doubled its price for a 20 to 30% speed gain, and its pass rate fell to 67.86%. GPT-5 had the best pass rate and took over three minutes per model.
Click on an image to inspect the model.
Gemini 3 became the default that week. It lasted until Gemini 3.1 in March 2026, which lasted until Opus 4.7 in April, then Gemini 3.6 Flash in July and Gemini 3.7 Flash in August. The leaderboard moves fast; the only way to keep up is to keep running the suite.
Want the next benchmark when it lands?
Or try the model that won.